LiLo-VLA: Compositional Long-Horizon Manipulation via Linked Object-Centric Policies
Chaining atomic skills through a motion planner, so unseen skill orderings run zero-shot.
Best Paper Award, IROS 2026 Compositional and Modular LearningAbstract
General-purpose robots must master long-horizon manipulation, defined as tasks involving multiple kinematic structure changes (e.g., attaching or detaching objects) in unstructured environments. While Vision-Language-Action (VLA) models offer the potential to master diverse atomic skills, they struggle with the combinatorial complexity of sequencing them and are prone to cascading failures due to environmental sensitivity. To address these challenges, we propose LiLo-VLA (Linked Local VLA), a modular framework capable of zero-shot generalization to novel long-horizon tasks without ever being trained on them. Our approach decouples transport from interaction: a Reaching Module handles global motion, while an Interaction Module employs an object-centric VLA to process isolated objects of interest, ensuring robustness against irrelevant visual features and invariance to spatial configurations. Crucially, this modularity facilitates robust failure recovery through dynamic replanning and skill reuse, effectively mitigating the cascading errors common in end-to-end approaches. We introduce a 21-task simulation benchmark consisting of two challenging suites: LIBERO-Long++ and Ultra-Long. In these simulations, LiLo-VLA achieves a 69% average success rate, outperforming Pi0.5 by 41% and OpenVLA-OFT by 67%. Furthermore, real-world evaluations across 8 long-horizon tasks demonstrate an average success rate of 85%.
- 85% vs 0%
- success on reordered skill sequences
- 69% / 86%
- overall success rate / average progress
- 16 skills
- longest task in the benchmark
- 85%
- on a real Franka Panda
LiLo-VLA vs Pi0.5 · same Suite-1 tasks, only the order changes
Pi0.5 28% / 31% · OpenVLA-OFT 2% / 4%
21 configurations over 9 scenarios · prior LIBERO-Long suites run 3–4
8 configurations, up to 8 skills, trained on atomic skills only
Overview — sound on
Reordering should be free
A long-horizon task is a sequence of atomic skills, and the same skills usually admit many valid orderings. Put the mug away before the bowl or after it; the skills are identical either way. A policy that has learned the skills should not care which order it is asked for.
Monolithic VLA policies care a great deal. Fine-tuned on the original long-horizon demonstrations of six LIBERO-Long++ tasks, Pi0.5 solves 83% of them. Ask for the same tasks with the skills in a different order and it solves none of them.
| Method | Original order | Reordered | Change |
|---|---|---|---|
| Pi0.5 | 83% | 0% | −83 pts |
| LiLo-VLA (ours) | 78% | 85% | +7 pts |
The failure has a specific cause rather than a mysterious one: Pi0.5 frequently ignores the re-ordered language instruction and replays the order it was trained on. It has memorised a trajectory, not grounded a command.
LiLo-VLA is never trained on a task-level ordering at all — only on individual atomic skills, each starting from a canonical approach pose that a motion planner is responsible for reaching. No ordering is more in-distribution than another, so the reordered sequences of Suite 1 score no worse than the original ones. Everything below follows from that one decision.
Linking object-centric policies
Execution is split in two. A Reaching Module moves the end-effector from wherever the last skill ended to a per-object approach pose, using a collision-aware motion planner over the scene point cloud (MPLib). An Interaction Module then performs the contact-rich part with an object-centric VLA policy. A geometric verifier checks each skill’s effect, and a closed-loop wrapper decides what to do when it fails.
Architecture. The Reaching Module plans a collision-free path to an approach pose defined in the reference object’s frame; the pose is perturbed during demonstration generation so the downstream policy tolerates planner and perception error. The Interaction Module then executes the atomic skill from a wrist view with non-target objects masked out. A failed skill falls back to the Reaching Module for a reset rather than a blind retry.
Reaching: transport, planned not learned
The approach pose is defined in the reference object’s frame — a fixed face-down orientation plus a skill-specific offset, such as a vertical clearance for a pick — so it is deterministic and reusable across orderings. MPLib plans a collision-free path to it from the environment point cloud and the robot’s kinematic chain, with nothing learned.
Planner convergence and pose estimation are never exact, so demonstrations are not generated from the canonical pose. Each episode starts from a perturbed pose sampled around it, and the policy absorbs the residual error. Aggregated over the 27 unique skills in both suites, the perturbation-trained policy shows only a marginal drop under initial-pose noise, while a policy trained on canonical trajectory endpoints degrades sharply.
Interaction: one object, one wrist view
The interaction policy sees the wrist camera only. Fixed third-person views are deliberately excluded: as the global layout and the end-effector position change from skill to skill, a static camera sees inconsistent features — the observation-space shift that long-horizon execution suffers from — while the wrist view keeps the target in frame and most distractors out of it.
Non-target objects are then masked with black rectangles derived from their segmentation masks. Because that masking is itself a large visual shift, training applies random erasing to background pixels only, so the masked observation at deployment stays inside the distribution the policy learned.
Recovery, not retry
Each skill ends with a geometric verifier: LIBERO’s own contact, position and height conditions for a place, displacement or rotation for an articulation, and an added predicate for a pick, which succeeds when the target rises by at least 3 cm.
When a skill fails, what happens next depends on whether the gripper is holding something. A failed pick or articulation is retried locally — the object pose is re-estimated and the Reaching Module returns the end-effector to the approach pose first, so the retry starts from a state the policy trained on. A failed place means the held object’s location is uncertain, so execution backtracks to the most recent pick and re-acquires it. Every skill position keeps its own retry counter that no other skill’s success resets, with a budget of K = 10, which bounds the whole episode at O(NK) failures.
Setup, backbones and what is assumed
- Backbone (simulation). OpenVLA-OFT with its original hyperparameters, fed the wrist view only, with random erasing on background pixels. Training data is LIBERO-90 demonstrations segmented into atomic skills and augmented through MPLib: perturbed initial states are sampled around the approach pose and planned back onto the original demonstrations, which bridges the planner-policy gap.
- Backbone (hardware). Pi0.5, trained on teleoperated atomic-skill demonstrations only. The framework is not bound to one architecture.
- Baselines. Pi0.5 and OpenVLA-OFT. On Suite 1 original sequences both are LoRA fine-tuned on the original continuous long-horizon demonstrations, and on variant sequences they are prompted zero-shot with the reordered instruction. On Suite 2, collecting continuous demonstrations for every permutation is combinatorially intractable, so both are trained on the aggregate atomic-skill dataset and chained at inference by prompting one sub-task description at a time.
- What is assumed in simulation. Simulator ground-truth poses and segmentation masks, so a reported failure traces to the policy or the planner rather than to upstream perception. Neither baseline receives those poses; the
w/o Reachingablation below does. - What is assumed on hardware. YOLOE for detection and segmentation, FoundationPose for 6D pose. Because occlusion prevents reliable automatic verification on hardware, a human operator judges whether each skill succeeded.
- The skill sequence is given. An external symbolic or LLM/VLM planner supplies it; this work is about executing it.
A benchmark of 21 configurations
The LIBERO-Long tasks this builds on stop at three or four skills. The benchmark here keeps that regime and adds one an order of magnitude longer, and every scenario ships with permuted skill orderings — those permutations are what no policy is trained on.
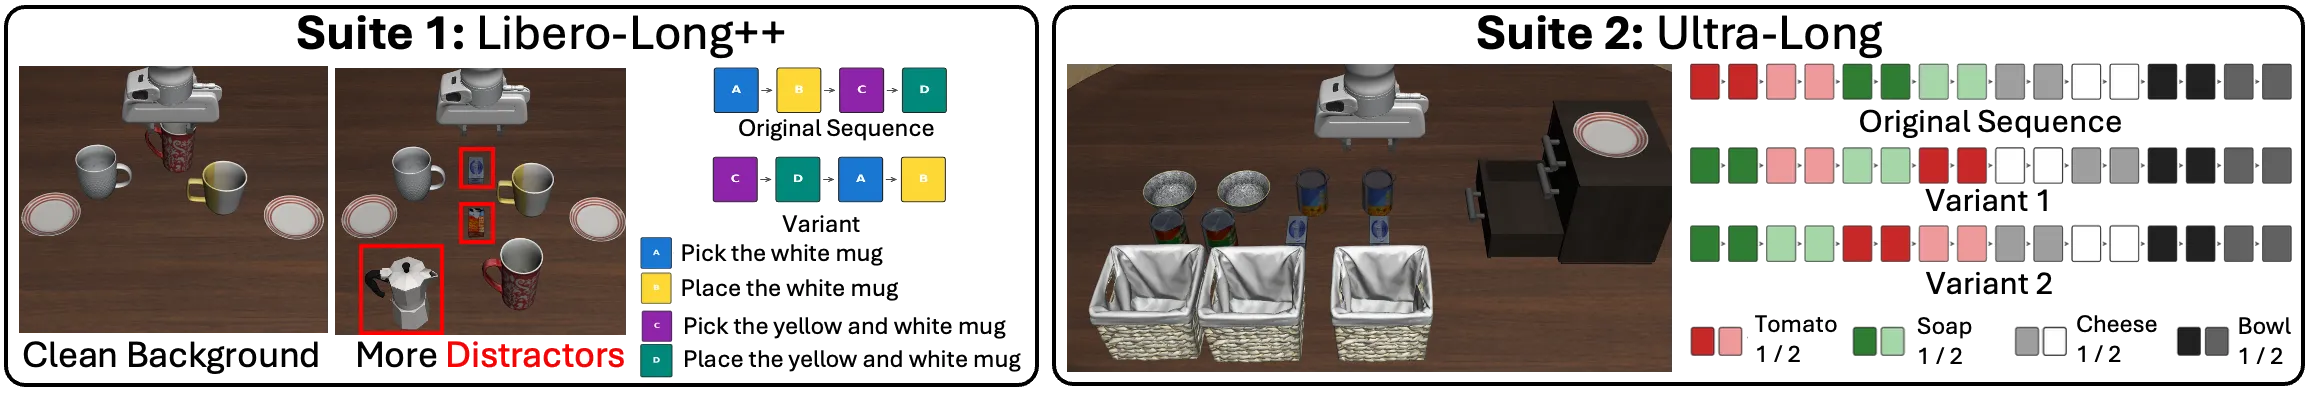
| Suite | Scenarios | Orderings each | Configurations | Skills per task |
|---|---|---|---|---|
| LIBERO-Long++ | 6 | 2 | 12 | 3–4 |
| Ultra-Long | 3 | 3 | 9 | 9–16 |
| Total | 9 | — | 21 | — |
The three Ultra-Long tasks
- Kitchen Organization — 9 skills. Dense receptacles: three baskets and a cabinet in one workspace.
- Cooking Preparation — 10 skills. Geometrically awkward objects, the Moka Pot above all, which is where picks go wrong.
- Living Room Organization — 16 skills. The longest chain in the benchmark, and the one where reachability, not perception, is the binding constraint.
Evaluation protocol
- 10 trials per configuration.
- SR counts an episode only if every skill in the sequence executes in the required order.
- AP (average progress) counts the uninterrupted prefix of correct skills and stops at the first out-of-order or failed one.
- Overall macro-averages the 9 scenarios, not the 21 configurations.
Results in simulation
| Suite 1 · LIBERO-Long++ | Suite 2 · Ultra-Long | |||||||
|---|---|---|---|---|---|---|---|---|
| Method | Original | Reordered | Avg. | Original | Reorder 1 | Reorder 2 | Avg. | Overall |
| Baseline · Pi0.5 | 83% AP 93% | 0% AP 0% | 42% AP 46% | 0% AP 1% | 0% AP 0% | 0% AP 0% | 0% AP 0.3% | 28% AP 31% |
| Baseline · OpenVLA-OFT | 7% AP 11% | 0% AP 0% | 3% AP 5% | 0% AP 0% | 0% AP 0% | 0% AP 0% | 0% AP 0% | 2% AP 4% |
| Ablation · w/o Reaching | 0% AP 0% | 0% AP 0% | 0% AP 0% | 0% AP 0% | 0% AP 0% | 0% AP 0% | 0% AP 0% | 0% AP 0% |
| Ablation · w/o Masking | 67% AP 80% | 77% AP 87% | 72% AP 83% | 0% AP 16% | 0% AP 32% | 0% AP 10% | 0% AP 20% | 48% AP 64% |
| Ablation · w/o Recovery | 2% AP 25% | 23% AP 59% | 13% AP 42% | 0% AP 16% | 0% AP 16% | 0% AP 21% | 0% AP 18% | 8% AP 33% |
| LiLo-VLA (ours) | 78% AP 88% | 85% AP 89% | 82% AP 89% | 53% AP 79% | 37% AP 84% | 43% AP 74% | 44% AP 79% | 69% AP 86% |
Two things in that table are worth reading slowly.
Suite 2 is not solved. Both baselines score 0% on every Ultra-Long configuration, and LiLo-VLA reaches 44%. The gap is attributable to coupling: as layouts evolve across stages, a policy that owns transport as well as interaction needs intractable amounts of transition data, whereas delegating transport to a planner leaves the interaction policy invariant to those shifts. But 44% means most 9-to-16-skill episodes still end short of the goal.
Read AP next to SR. Suite 2 averages 44% SR at 79% AP — a typical trial completes about four fifths of its sequence. At these horizons SR collapses each trial to a single bit and discards most of the signal; AP is the more informative, and the more stable, number.
What each module buys
Each ablation removes one component and leaves the rest of the system intact.
Knowing where the object is does not help. The w/o Reaching ablation hands the whole episode to the Interaction Module and is granted the same ground-truth object poses the full method uses. It scores 0% on all 21 configurations. A VLA trained on atomic-skill demonstrations does not learn long-horizon transport from pose knowledge alone, so the motion planner is a structural prerequisite rather than an accelerator — and the oracle poses LiLo-VLA is given in simulation are not what the results rest on.
Masking matters on top of viewpoint. Removing random erasing costs 21 points overall, 69% to 48%, and takes Suite 2 to 0%. Even a wrist camera admits enough of the surrounding scene that object-centricity has to be enforced explicitly.
Recovery is not just more tries. A naive-retry control keeps the same budget of K = 10 but re-runs a failed skill from wherever the arm ended up, without re-estimating the object pose, resetting to the approach pose, or backtracking to the last pick:
| Retry policy | Success rate | Average progress |
|---|---|---|
| Naive retry (same K = 10) | 23% | 52% |
| LiLo-VLA closed-loop recovery | 53% | 79% |
Across the three Ultra-Long scenarios recovery triggers on 26.8% of executed skills and resolves 79.2% of them, and the yield is bounded by the atomic policy underneath it: Cooking Preparation triggers most often, on 37.5% of skills, and resolves only 46.7%, because some picks on geometrically complex objects never succeed.
Why wrist-only. On BOSS-C1, a benchmark that stress-tests policies against observation-space shift:
| Observation | Relative drop under observation-space shift |
|---|---|
| Wrist only (ours) | 15.9% |
| Wrist + 3rd person | 18.8% |
| 3rd person only | 29.8% |
Real-robot deployment
A Franka Emika Panda with a Robotiq 2F-85 gripper and the dual-camera setup of DROID: a static ZED 2 gives the Reaching Module global context, and a wrist-mounted ZED Mini feeds the Interaction Module. Two things differ from simulation, and both are the point of this section — the backbone is Pi0.5 rather than OpenVLA-OFT, so the framework does not bind to one architecture, and the training data is teleoperated atomic skills only, with no long-horizon sequence data at all.
| Scene | Standard | Change Sequence | Diverse Layout |
|---|---|---|---|
| Scene A · 4 skills | 100% AP 100% | 80% AP 80% | 100% AP 100% |
| Scene B · 4 skills | 100% AP 100% | 60% AP 90% | 80% AP 95% |
| Scene C · 8 skills | 100% AP 100% | 60% AP 85% | — |
Every rollout below is real hardware. Clips play as they scroll into view; each carries its task number and protocol in the frame, with the measured success rate overlaid.
Scene A · 4 skills
Scene B · 4 skills
Scene C · 8 skills
Run your own policy on it
The benchmark ships separately from the method. Evaluating your own policy on the 21 configurations needs neither the LiLo-VLA framework nor a GPU-sized dependency tree.
git clone https://github.com/YY-GX/LiLo-VLA.git && cd LiLo-VLApip install -e ".[libero]" # 9 packages, not 39import lilo_vla.benchmark # registers the suites AND patches LIBEROfrom libero.libero.benchmark import get_benchmark
bench = get_benchmark("ultra_long")() # or "libero_long_plus_plus", # "ultra_long_all", "libero_long_plus_plus_all"for i in range(bench.get_num_tasks()): task = bench.get_task(i) env, obs = bench.make_env(i) # the published evaluation protocol # ... roll out YOUR policy ... success = env.env._check_success() env.close()make_env() builds the environment exactly as every number on this page was measured, so results are comparable without matching a protocol by hand. Importing lilo_vla also applies the LIBERO compatibility patches the benchmark depends on — three of them change success criteria, so an unpatched LIBERO does not crash, it silently scores the same rollouts differently. The checkpoint and the atomic-skill dataset are released alongside it.
Limitations
- Perception is external. On hardware the Reaching Module plans from detections and 6D poses supplied by YOLOE and FoundationPose, which struggle with transparent or occluded objects.
- Recovery cannot exceed the atomic policy. The backbone’s proficiency at a single skill caps what closed-loop recovery can achieve: with per-skill success and budget , the recovered rate is , which stays 0 for any when is 0.
- Verification is geometric, and human on hardware. Each skill is checked against BDDL predicates in simulation; on the real robot an operator judges success, because occlusion prevents reliable automatic verification.
A natural extension integrates an LLM/VLM planner that produces the skill sequence, and evaluates planning and execution end to end.
Takeaway
- Problem. A monolithic VLA memorises the ordering it was trained on: Pi0.5 goes from 83% to 0% when the same six tasks are reordered, and to 0% everywhere once a task runs past a handful of skills.
- Method. Delegate transport to a collision-aware motion planner, confine the learned policy to one masked, object-centric wrist view, and close the loop with a verifier that resets to a known state before retrying.
- Benchmark. 21 configurations over 9 scenarios, including three Ultra-Long tasks of 9, 10 and 16 skills, all with permuted orderings that nothing is trained on.
- Result. 69% SR and 86% AP in simulation against 28% for Pi0.5 and 2% for OpenVLA-OFT, and 85% across 8 real-robot configurations with a different backbone and atomic-skill data only.
BibTeX
@article{yang2026lilo, title={LiLo-VLA: Compositional Long-Horizon Manipulation via Linked Object-Centric Policies}, author={Yang, Yue and Cheng, Shuo and Fang, Yu and Bharadhwaj, Homanga and Ding, Mingyu and Bertasius, Gedas and Szafir, Daniel}, journal={arXiv preprint arXiv:2602.21531}, year={2026}}